Yequan Zhao

About

I am a Ph.D. student in ECE at UC Santa Barbara, advised by Prof. Zheng Zhang. I work on memory- and energy-efficient training.

My core direction is back-propagation-free (BP-free) training: gradients are estimated from forward passes alone (zeroth-order optimization), which makes on-device training a plug-in over an inference accelerator: a training engine needs little more than the inference engine already on the chip. I apply it to:

I also work on efficient LLM fine-tuning and optimizers (FuRA, Muon²), and have interned at Amazon Lab126 and Hewlett Packard Labs.

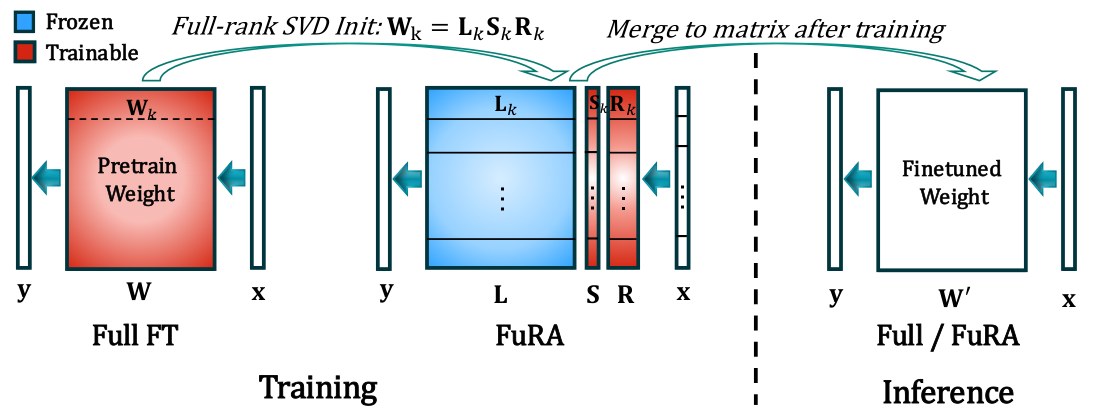
FuRA replaces each linear layer with a block tensor-train factorization W = L S R

FuRA: full-rank PEFT

TL;DR LoRA-level cost, Full-FT-level performance (+1.37 over Full FT on LLaMA-3-8B). Each layer is factored as W = L·S·R with L fixed to the pretrained SVD basis; training only S and R gives full-rank, spectrally preconditioned updates.
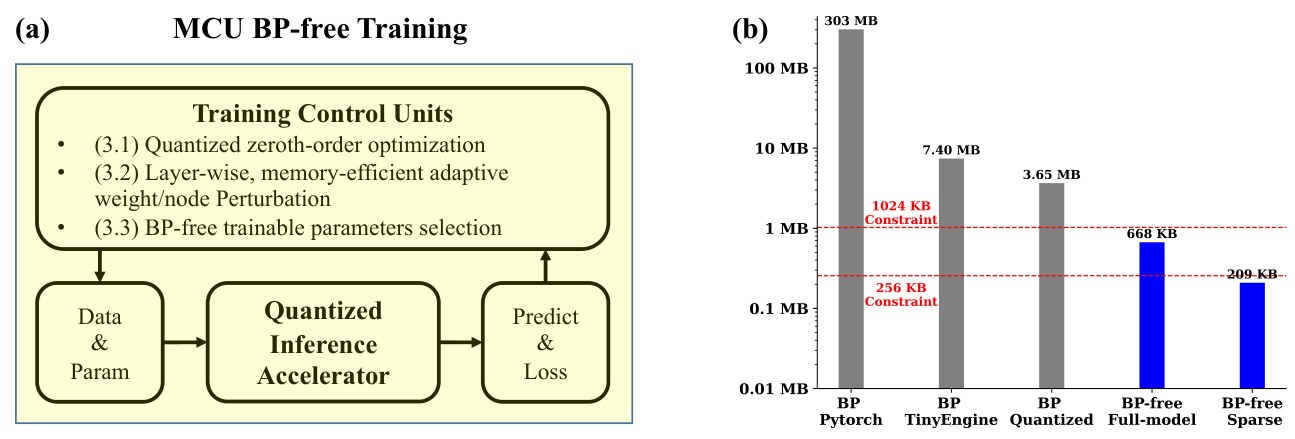
(a) MCU BP-free training framework and (b) training memory comparison

BP-free training on MCUs

TL;DR Add a control unit and repeated forward passes to a quantized inference engine and it becomes a training engine. Full-model training fits in 1 MB SRAM (sparse: 256 KB) and matches BP accuracy.

ACM TODAES 2025 →
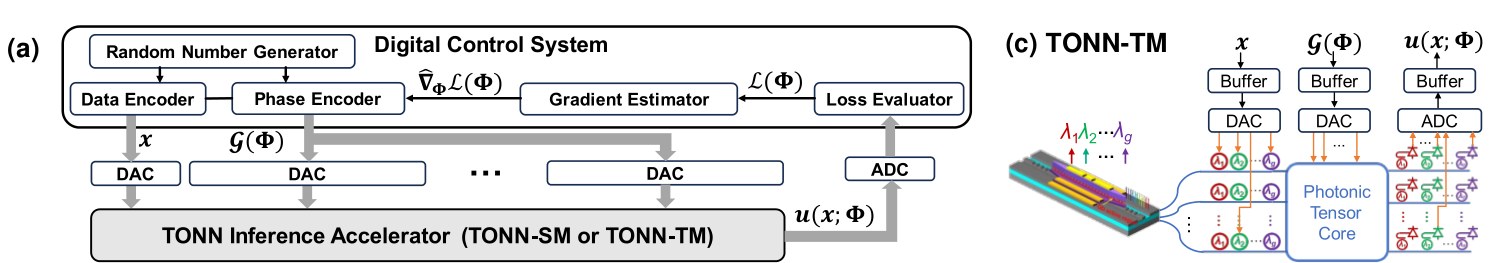
(a) BP-free optical training accelerator and (c) TONN time-multiplexing architecture

BP-free optical PINN training

TL;DR A sparse-grid Stein estimator removes BP from the PINN loss, and tensor-train ZO training keeps the search space small. Together they enable real-size PINN training on photonic tensor cores.

ACM TODAES 2026 →

News

  • 🎉 FuRA is accepted by NeurIPS 2026. Project page · Code.
  • 🎉 Muon² is accepted by EMNLP 2026 as an Oral presentation.
  • 🏆 Received the ACM TODAES Rookie Author of the Year award.
  • 🏆 Received the UCSB ECE Wallace Kou Graduate Fellowship.
  • 💼 Returned to Amazon Lab126 as an Applied Scientist Intern, working on MoE serving on edge GPUs.
  • 🎉 Optical PINN training paper published in ACM TODAES; SkipKV appears at MLSys 2026.
  • 🎉 QuZO at EMNLP 2025; Poor Man's Training on MCUs in ACM TODAES; on-chip PINN demo at OFC 2025.
  • 💼 Joined Amazon Lab126 as an Applied Scientist Intern (LLM compression).
  • 💼 Joined HPE Large-scale Integrated Photonics Lab as a Research Associate Intern.
  • 🎓 Started my Ph.D. at UC Santa Barbara.

Education & Experience

Industry

  • 2026.06 – 2026.09Applied Scientist Intern · Amazon Lab126Efficient mixture-of-experts serving on edge GPUs. Mentors: Sankalp Dayal, Tong Qin.
  • 2025.06 – 2025.09Applied Scientist Intern · Amazon Lab126LLM compression via tensor decomposition and knowledge distillation. Mentors: Sankalp Dayal, Tong Qin.
  • 2024.07 – 2024.09Research Associate Intern · Hewlett Packard EnterpriseLarge-scale Integrated Photonics Lab. Optical neural PDE solver via on-chip PINN training. Mentors: Dr. Xian Xiao, Dr. Geza Kurczveil.

Education

  • 2023.09 – presentPh.D., Electrical & Computer EngineeringUniversity of California, Santa BarbaraAdvisor: Prof. Zheng Zhang · GPA 3.96/4.0

Publications

★ first-author work. * equal contribution.

2026
2025
2024 & earlier

Honors & Service

Awards

  • 2026ACM TODAES Rookie Author of the Year
  • 2026UCSB ECE Wallace Kou Graduate Fellowship

Reviewer

  • Conf.NeurIPS 2026, AAAI 2026
  • JournalIEEE TPAMI, IEEE TAI